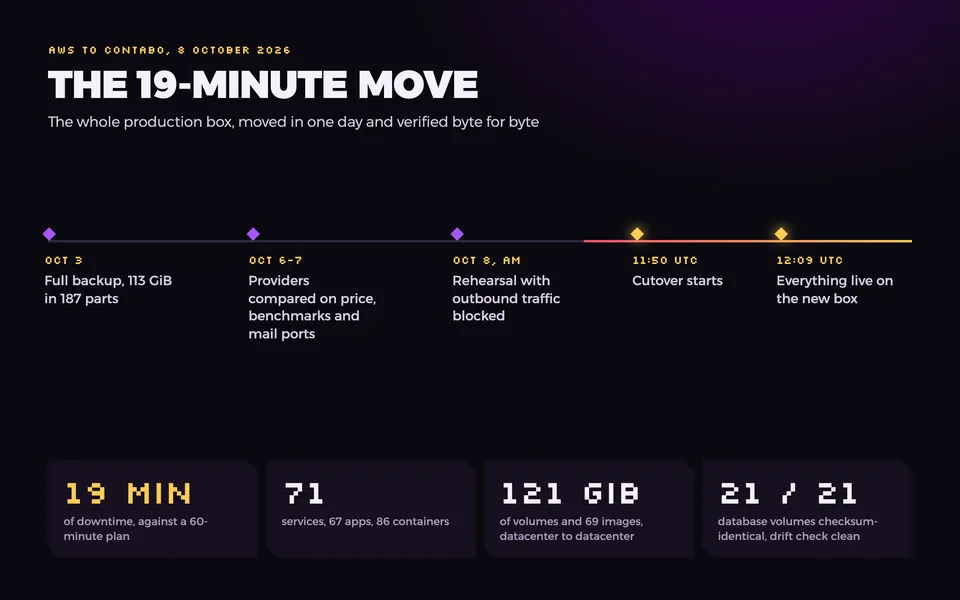
The story
Everything moved in one day: CapRover with every app, GitLab, Nextcloud, mail, the Supabase stack and every database. The outage ran from 11:50 to 12:09 UTC against a plan of 45 to 60 minutes, and clients on stale DNS still reached the new box through forwarding.
Hard parts cleared
- Nothing could be sent twice: during the rehearsal the new box ran with outbound traffic blocked, so cloned apps could not send mail, pushes or webhooks.
- 69 images and 59 volumes moved byte for byte, datacenter to datacenter, with a warm sync first and a final one after a clean stop.
- A drift check compared every service spec old against new and came back clean; 21 database volumes were checksum-verified.
- Cutover without waiting for DNS: the old box forwarded every port except SSH to the new one, so the outage ended when forwarding began.